

Amazon Polly charges by the character, and the price depends almost entirely on which voice engine you pick: $4 per million characters for Standard voices, up to $100 for Long-Form. Most people searching for Polly’s price are deciding between those engines, or deciding whether to leave. This page covers both: Polly’s current pricing and free tier first, then 11 alternatives and what to check before switching.
Amazon Polly pricing and free tier
Prices and allowances from the AWS Polly pricing page, checked October 5, 2026:
| Voice engine | Price per 1M characters | Free tier per month |
|---|---|---|
| Standard | $4 | 5M characters |
| Neural | $16 | 1M characters, first 12 months |
| Generative | $30 | 100K characters, first 12 months |
| Long-Form | $100 | 500K characters, first 12 months |
A few things the table doesn’t show:
- Only Standard’s free tier lasts. The Neural, Generative, and Long-Form allowances end 12 months after you open the account. Standard keeps its 5 million characters per month.
- New accounts get credits. Since July 15, 2025, new AWS customers can get up to $200 in AWS Free Tier credits, which apply to Polly. On the free plan, the account closes after six months or when the credits run out, unless you upgrade.
- A million characters is about 23 hours of audio. That’s AWS’s own estimate. At that rate, Neural speech costs about $0.70 per hour, and Generative about $1.30.
- Speech Marks cost the same as speech. Requests for word or viseme timing are billed per character at the same rate (Generative voices don’t support them).
Polly’s Standard voices are hard to beat on price. If they sound good enough for your use case, and you’re already on AWS, you may not need to switch. People usually look elsewhere for three reasons: they need speech that sounds more natural than Standard or Neural, they need lower latency for a live conversation, or they need a custom or cloned voice.
What to compare
Polly is part of AWS, which can simplify access and billing for an existing AWS application. Cartesia is worth testing when you want Sonic for generated speech or custom voices. Budget for integration work as well as API usage.
The options below cover different jobs; they are not a ranked benchmark. Check each provider’s current availability, features, and plan terms before committing.
Alternatives at a glance
| Product | Evaluate for | Check before choosing |
|---|---|---|
| Cartesia | Speech for voice applications | Model, language, and integration requirements |
| Murf AI | Scripted voiceovers | Editing controls and export rights |
| Speechify | Reading documents aloud | Reading app, studio, or API plan |
| ElevenLabs | Voice generation and dubbing | Model choice and usage limits |
| Google Cloud Text-to-Speech | TTS in Google Cloud applications | Voice-specific features and quotas |
| Microsoft Azure Text-to-Speech | Speech in Azure applications | Region, SSML support, and custom voice access |
| IBM Watson Text to Speech | TTS API integration | Languages, controls, and service limits |
| WellSaid Labs | Business voiceovers | Team workflow and language coverage |
| NaturalReader | Document listening | File support and personal versus commercial rights |
| iSpeech | Speech API integration | Current API support and availability |
| Descript | Transcript-based media editing | Editing workflow and export options |
Cartesia
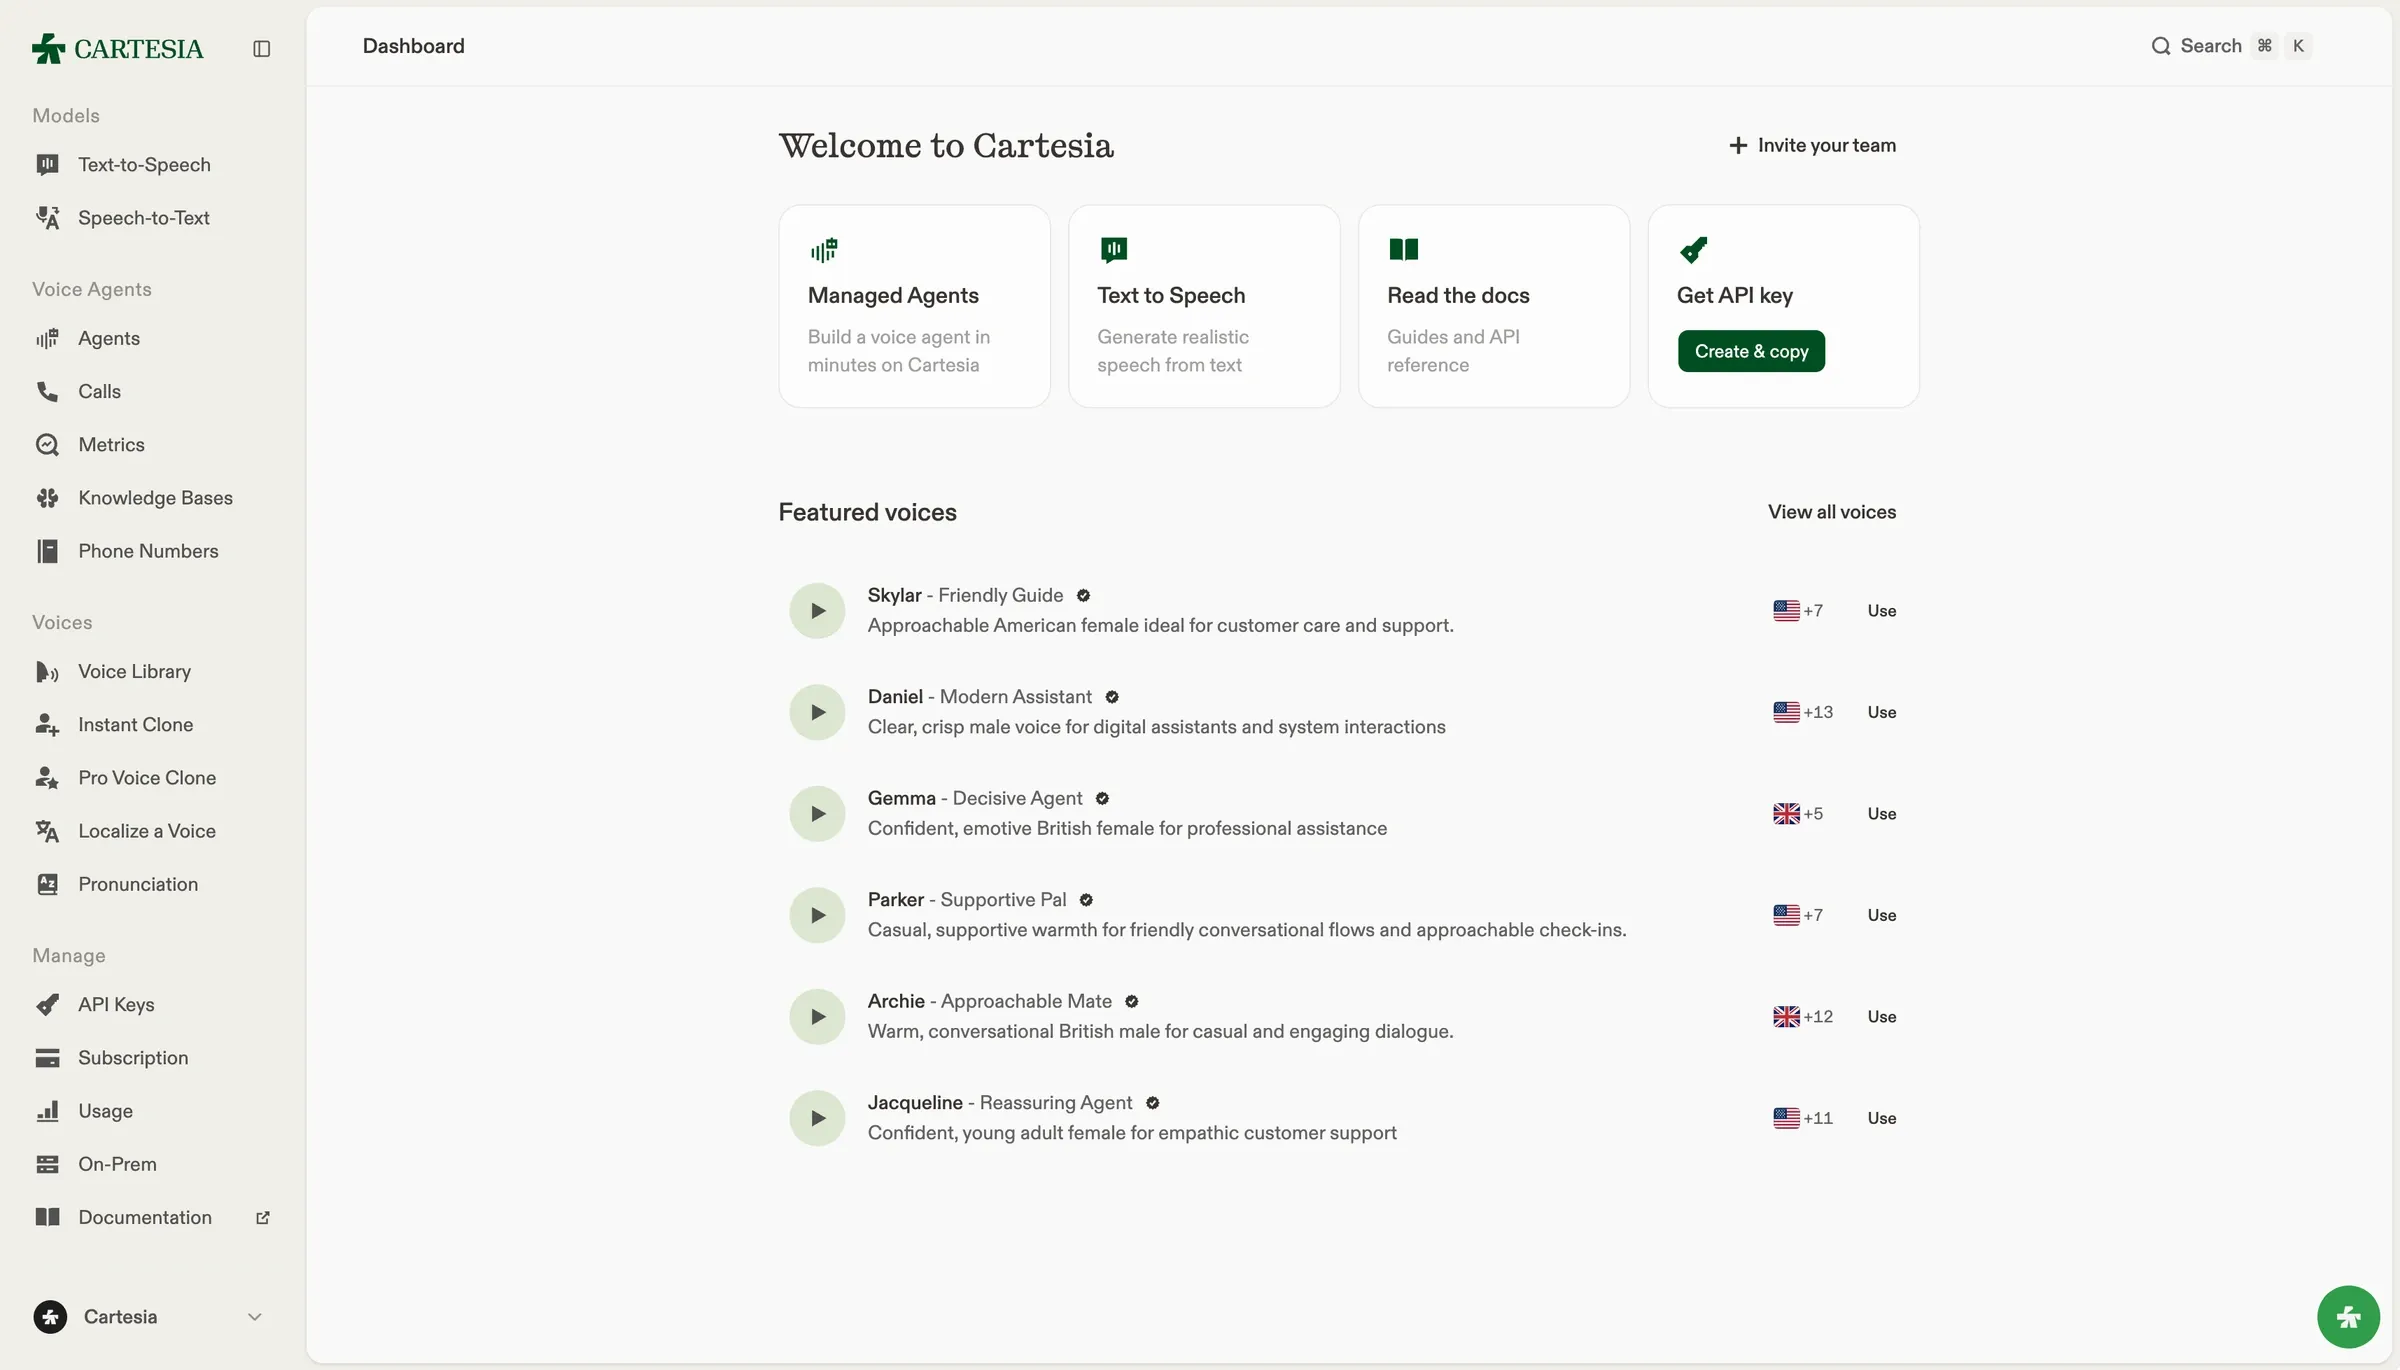
We build Sonic, a text-to-speech model for voice applications. You can stream generated audio, select a voice, or use voice cloning with recordings you have permission to use. Try your own text in the playground before integrating the API.
For a complete voice agent, you also need speech recognition and conversation handling. Ink is our speech-to-text model, and Managed Agents is our voice agent builder. Sonic alone does not listen to callers or decide what to say.
Check language coverage, API requirements, and pricing for the model and plan you intend to use. Measure response time in your application: network travel and playback buffering contribute to what a user hears.
Murf AI
Murf AI has a voiceover editor for working from scripts and matching narration to media. Consider it for training materials and recorded presentations. Test how much editing your script needs, and check whether the plan includes the exports and team access you need.
Speechify
Speechify has reading apps that turn documents and web pages into audio. If your goal is to listen to existing text, start with that workflow. Evaluate its reading, studio, and API products separately; access to one does not tell you what another includes.
ElevenLabs
ElevenLabs has text-to-speech, voice cloning, and dubbing tools, as well as products for conversational applications. Compare the specific model and endpoint you would deploy. Test pronunciation and response time with your own scripts rather than treating every model as interchangeable.
Google Cloud Text-to-Speech
Google Cloud Text-to-Speech provides speech synthesis through Google Cloud APIs. For an existing Google Cloud application, account and billing integration may simplify adoption. Confirm that your chosen voice supports the language, streaming behavior, and speech controls your application needs.
Microsoft Azure Text-to-Speech
Microsoft Azure provides text-to-speech through its speech services. It is a candidate for teams already operating in Azure. Check the selected voice and region, supported Speech Synthesis Markup Language (SSML) controls, and access requirements for custom voices.
IBM Watson Text to Speech
IBM Watson Text to Speech is an API for generating speech from text. Include it if you are comparing speech services for an IBM-based deployment. Verify supported languages and pronunciation controls, then test output formats and service limits against your application.
WellSaid Labs
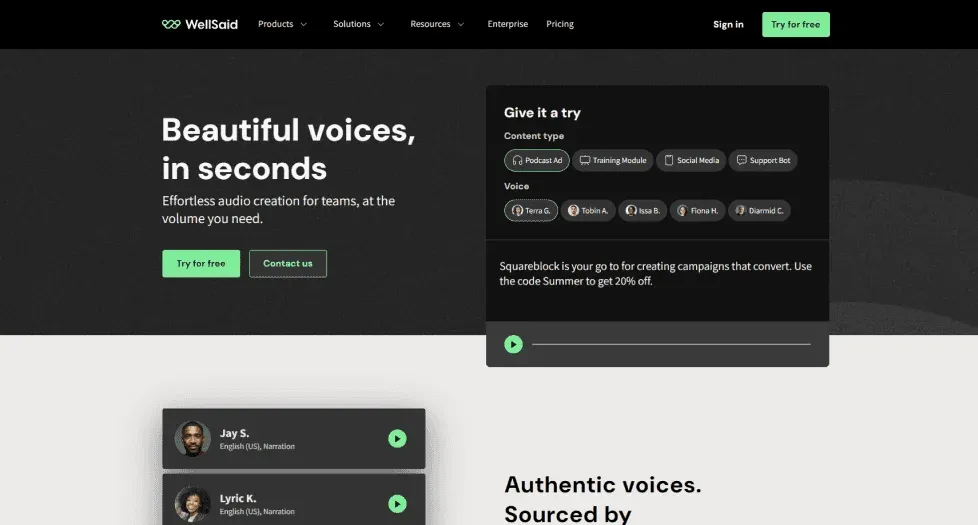
WellSaid Labs focuses on voiceover production for business content, including training and internal communications. Evaluate how your team reviews scripts and handles pronunciation changes. Check language coverage and API access for the plan you intend to use.
NaturalReader
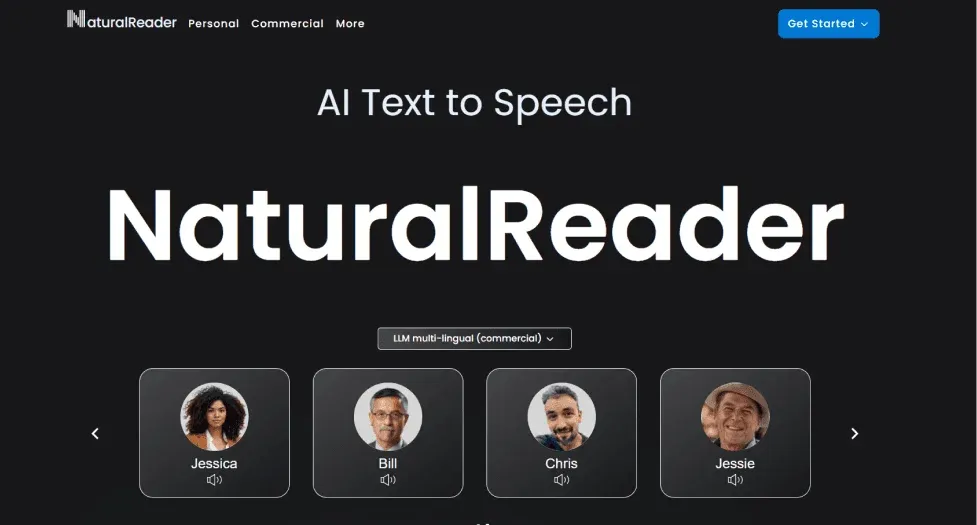
NaturalReader has tools for listening to documents and generating speech. Separate personal reading from commercial audio production when comparing plans. Test the file types you actually use; reading a scanned PDF also requires text recognition before speech synthesis.
iSpeech
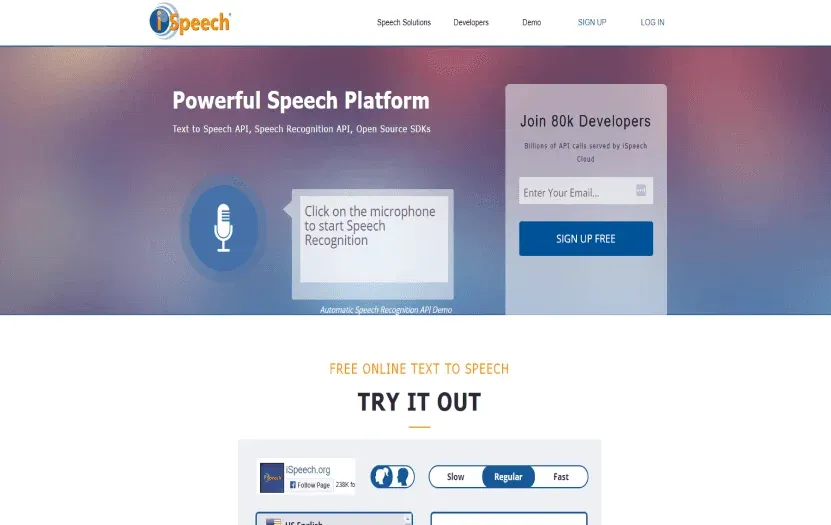
iSpeech is another speech API provider to investigate for an application integration. Confirm current documentation, SDK support, and service availability before implementation. Test the exact output format and language your application needs.
Descript
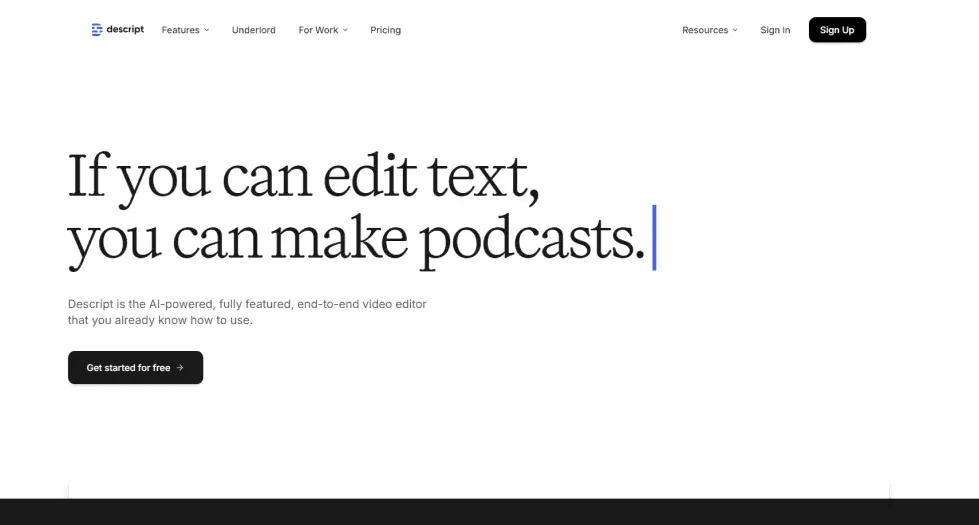
Descript combines transcription with text-based audio and video editing. Consider it when you want to cut recorded material by editing its transcript. A speech API alone will not replace that editor, so test the recording-to-export workflow before switching.
Test before you switch
Inventory the Polly features your application uses. Test each SSML instruction and pronunciation rule against the new provider instead of forwarding it unchanged. Confirm sample rate and encoding at the playback layer, then compare response time and cost using the same traffic sample.
Compare cost using your expected usage and the features you need. Include retries, regenerated audio, concurrency limits, and commercial rights. A low starting price is not a workload estimate.